Pitch Deck

Mutagent

Your agent factory.

Spec
Dr.-Ing. Benedikt Sanftl Burak Ozafsar
bene@mutagent.io
The Problem

Shipping an agent takes a weekend. Keeping a fleet of them working takes a system.

62% of enterprises are experimenting with AI agents. Only 23% are scaling. Gartner expects more than 40% of agentic AI projects to be cancelled by 2027

Operating

Every agent needs its own eval suite, its own dataset and a judge somebody calibrated. Built by hand that is 3–4 developer days per agent, every month — and the team does not grow with the fleet.

Managing

Versions, rollbacks and model drift, across every agent and every engineer. Each one is built a different way, so there is no shared standard and no shared history to roll back to.

Optimising

Every fix is hand-run and scoped to one agent. Nothing compounds: what you learned fixing the last agent does not reach the next one, which starts again from zero.

Agents running in production 2026
15Magents
15Mwe are here 2029 · 1B
The Solution

Meet Mutagent, agent development automated.

Mutagent is your agent factory.

Coding harness for AI agent development

Specialised commands and instructions to drive the complete agent development lifecycle in a loop. Runs local for development and in the cloud at scale.

Build, diagnose and optimise agents

Mine evals, create test datasets, find failures in real traces, fix them and evaluate them on test data before shipping.

Cloud infrastructure to monitor and manage at scale

Monitor agents in production, diagnose failures, automatically optimize them. The engineer just approves the changes.

An agent factory is a fleet of agents wired to your agent development lifecycle — triggered by an issue, a Slack message, or a schedule, and coordinated from triage through review to a mergeable PR.

The Product

Develop local. Agent factory in the cloud.

Build and optimise one agent on your machine. Monitor and manage the whole fleet in the cloud.

HelixCoding harness · local
helix
/optimize My support agent keeps routing tickets to the wrong team
Scanning 847 traces...
Found 47 traces with the same failure pattern. 73% of misrouted tickets contain "billing" + "refund" together.
Root cause: the routing prompt says "consider" instead of "must". The agent treats it as a suggestion, not a rule.
Fix prepared: Changed "consider routing to billing" to "MUST route to billing when refund is mentioned". Added 3 test cases.
Running 60 experiments...
Accuracy 61% → 89%. Zero regressions. PR generated.
Apply the fix?
Looks good, apply it
Fix applied. PR merged. Agent updated in production.
Agent factoryCloud · at scale
Helix agent development lifecycle orchestration
/spec
/build
/eval
/diagnose
/optimize
/ship
LIVE
support-router
support-triage
support-handler
support-classifier
billing-router
billing-triage
billing-handler
billing-classifier
refund-router
refund-triage
refund-handler
refund-classifier
onboarding-router
onboarding-triage
onboarding-handler
onboarding-classifier
docs-router
docs-triage
docs-handler
docs-classifier
email-router
email-triage
email-handler
email-classifier
sales-router
sales-triage
sales-handler
sales-classifier
invoice-router
invoice-triage
invoice-handler
invoice-classifier
contract-router
contract-triage
contract-handler
contract-classifier
ticket-router
ticket-triage
ticket-handler
ticket-classifier
churn-router
churn-triage
churn-handler
churn-classifier
kyc-router
kyc-triage
kyc-handler
kyc-classifier
pricing-router
pricing-triage
pricing-handler
pricing-classifier
shipping-router
shipping-triage
shipping-handler
shipping-classifier
faq-router
faq-triage
faq-handler
faq-classifier
sentiment-router
sentiment-triage
sentiment-handler
sentiment-classifier
resume-router
resume-triage
resume-handler
resume-classifier
meeting-router
meeting-triage
meeting-handler
meeting-classifier
expense-router
expense-triage
expense-handler
expense-classifier
inventory-router
inventory-triage
inventory-handler
inventory-classifier
80 agents monitored · 8 active · 1,898 optimisations shipped
Traces
LangfuseOTELDash0DatadogLangSmithBraintrust
Agents
LangChainClaude CodeCodexCursorMastraVercel
Try it out Paste into your coding agent
npm install -g @mutagent/cli, tell me what I can do and manage my agent
Market Opportunity

The $52B AI agent infrastructure wave is creating a $3.1B quality layer.

We build the quality tooling layer, historically capturing ~6% of the infrastructure it serves.

AI Agents Market
2026
$10.9B
2030
$52B
2033
$183B (46% CAGR)

Why now

15M → 1B
Increase of AI agents from 2025 to 2029
18% → 60%
eval tooling adoption from 2026 to 2028
$600M+
VC invested in evaluation & observability market
AI Quality Market
AI Agent Market (2030) $52B
× Historic quality layer ratio ~6%
= TAM $3.1B
× Adoption by 2030 ~70%
= SAM $2.2B
SOM Y3 · bottom-up
$31M ARR
~4,660 teams × $556/mo
2033 horizon: $183B × 6% = $11B TAM
Competition

Everyone observes. Many evaluate. Some suggest. Mutagent acts.

$600M+ has gone into tools that show you the problem. None of them build the agent, and none of them keep it working.

Dashboards Show what happened. You figure out the rest.
Smart Monitors Auto-detect problems. Can't fix them.
Power Tools Can optimize, but only when you drive them.
Autonomous Engineers Find, diagnose, and fix problems independently.
ManualHuman does everything. Product is a viewer or editor.
AI-AssistedAI recommends and drafts. Human reviews, decides, triggers.
AutonomousAI runs independently. Human sets goals, system executes.
Langfuse$4.5M

Most popular open-source LLM observability platform with rich tracing, LLM-as-Judge scoring, and prompt versioning, but no path from insights to improvements.

Observe → Optimize4/10

Tracing, LLM-as-Judge, prompt versioning, and experiment tracking, but stops at measuring quality with no diagnosis or fix suggestions.

Manual → Autonomous4/10

Dashboard templates and annotation queues accelerate manual workflows, but every evaluation and improvement action requires human initiation.

Langfuse
HoneyHive$7.4M

Agent observability with distributed tracing across 100+ LLM providers, comprehensive monitoring but the improvement loop is entirely manual.

Observe → Optimize4/10

OpenTelemetry tracing, 20+ evaluators, and CI/CD regression detection that measures quality but never explains failures or suggests fixes.

Manual → Autonomous4/10

Pre-built evaluators with expert annotation routing and Slack alerts, but all remediation decisions and actions are human-driven.

HoneyHive
Orq$8.5M

European LLMOps platform connecting 150+ LLM providers with evaluation, observability, and guardrails but no optimization capabilities.

Observe → Optimize4/10

LLM-as-Judge evaluators, custom Python eval logic, and compliance guardrails, but no diagnosis or fix generation features.

Manual → Autonomous4/10

Evaluator libraries and AI Router for dynamic model selection, but all experimentation and improvement workflows are manually initiated.

Orq
Braintrust$121M

Well-funded eval platform with Autoevals OSS library, proprietary Brainstore DB (329x faster), and Loop AI for on-demand log exploration and Playground iteration.

Observe → Optimize4/10

Proprietary Autoevals scoring, online eval, and CI regression detection with Loop AI for log exploration, but no structured RCA confirmed across 549 docs pages.

Manual → Autonomous5/10

Loop provides on-demand AI assistance (generates scorers, datasets, prompt suggestions when asked), online scoring runs continuously, but Loop is user-initiated, not proactive.

Braintrust
W&B WeaveAcq. $1.7B

Weights & Biases GenAI platform acquired by CoreWeave for $1.7B with mature tracing and evaluation but no optimization or autonomous features.

Observe → Optimize5/10

Auto-instrumented tracing, rich scorer framework with leaderboards, and basic error taxonomy, but no fix suggestions or optimization.

Manual → Autonomous4/10

Auto-instrumentation and pre-built scorers reduce setup effort, but all analysis, investigation, and iteration remain fully human-driven.

W&B Weave
Patronus AI$40.1M

Enterprise evaluation with proprietary fine-tuned judge models (Lynx for hallucination, Glider 3B judge, Judge-Image for multimodal) and Percival copilot that detects 20+ failure modes.

Observe → Optimize5/10

Industry-leading custom eval models plus Percival that categorizes 20+ failure types. Failure taxonomy with pattern-matched prompt fixes, but not structured causal analysis.

Manual → Autonomous5/10

Percival provides on-demand AI-assisted failure analysis ("click Analyze with Percival"), with rich evaluator library and adversarial datasets, but all remediation requires manual action.

Patronus AI
Confident AI$2.2M

Open-source DeepEval library with 50+ custom eval metrics, red teaming, and built-in prompt optimization using GEPA and MIPROv2 algorithms adapted from Stanford DSPy research.

Observe → Optimize5/10

PromptOptimizer with GEPA/MIPROv2 generates prompt variants, but blind search over prompt space with no RCA or system understanding. Manual setup with goldens and callbacks required.

Manual → Autonomous4/10

CI/CD integration runs evaluations automatically on PRs, but optimization requires manual dataset preparation and human triggering of every optimization run.

Confident AI
Deepchecks$14M

LLM evaluation with an Insights Engine that generates performance summaries, detects weak segments, runs three-layer failure mode analysis, and suggests prompt improvements.

Observe → Optimize6/10

Three-layer RCA: Weak Segments + Property-Level + Version-Level failure mode analysis with representative examples and co-occurrence recommendations. Structured multi-level diagnosis.

Manual → Autonomous4/10

YAML-configurable auto-annotation pipelines and LLM-powered annotation, but user drives every significant action. Insights surface within configured pipelines, not proactively.

Deepchecks
DatadogPublic

The $42B APM giant with LLM Observability as an add-on, bringing enterprise-grade tracing and alerting to AI workloads but no AI-specific evaluation or optimization.

Observe → Optimize4/10

LLM tracing, cost tracking, and cluster visualization through existing APM infrastructure with basic LLM-as-Judge but no AI-specific diagnosis or optimization.

Manual → Autonomous4/10

Enterprise alerting with Automations that route and classify traces, but all improvement decisions are entirely human.

Datadog
Arthur AI$60.3M

AI monitoring and evaluation with continuous production scoring, but zero diagnosis or optimization capabilities despite $60M raised.

Observe → Optimize4/10

Mature eval framework with LLM-as-Judge, custom SQL/Python metrics, and prompt A/B experiments, but zero documentation on diagnosis or optimization.

Manual → Autonomous5/10

Continuous evaluations auto-run on every production trace with proactive webhook alerts, but the platform never generates insights or suggests improvements.

Arthur AI
Openlayer$19.4M

Gartner-recognized AI governance platform with 100+ automated tests and CI/CD quality gates, strong on compliance (ISO, OWASP, EU AI Act) but no fix generation.

Observe → Optimize4/10

100+ pre-built tests covering hallucination, toxicity, and bias with CI/CD regression testing that blocks bad deployments, but no diagnosis or fix generation.

Manual → Autonomous5/10

CI/CD runs thousands of tests per PR automatically with AI-suggested tests on setup and adaptive thresholds, but no proactive insight surfacing during ongoing work.

Openlayer
Judgment Labs$30M+

Agent behavior monitoring platform (Judgeval) with LLM-as-Judge scoring that continuously evaluates and alerts on agent misbehavior, but all remediation is human-driven.

Observe → Optimize5/10

Production monitoring with LLM judges, trajectory grouping, and anomaly highlighting, but the "Optimization" feature is manual prompt versioning, not automated optimization.

Manual → Autonomous6/10

Monitors production agents continuously with automatic LLM-judge evaluation and multi-channel alerting, but all remediation and fixes remain human-driven.

Judgment Labs
Fiddler AI$100M

Enterprise AI Control Plane with real-time guardrails that auto-block, reroute, or escalate bad outputs at <100ms, strong monitoring but no optimization.

Observe → Optimize5/10

100+ metrics, LLM-as-Judge, and hierarchical drill-down with guardrails that actively intervene, but no diagnosis of root causes or system-level optimization.

Manual → Autonomous6/10

Fiddler Trust Service guardrails auto-enforce safety policies without human intervention and continuous monitoring runs proactively, but improvement workflow is human-driven.

Fiddler AI
Raindrop AI$15M

"Sentry for AI agents" with custom ML classifiers scanning every session, Self-Diagnostics where agents proactively self-report failures, and Deep Search across millions of interactions.

Observe → Optimize5/10

Seven default signal classifiers, custom Deep Search classifiers, and Self-Diagnostics with 4 failure categories (missing_context, broken_tool, capability_gap, task_failure), but never suggests or generates fixes.

Manual → Autonomous7/10

Autonomous detection: signals run on every event, classifiers auto-scan all data, agents self-report failures, daily Slack digests fire automatically. But all remediation is manual: detection, not correction.

Raindrop AI
Galileo$50M+

Evaluation platform with proprietary Luna-2 SLM judges (97% cheaper evals) and Galileo Protect guardrails that auto-enforce, but no prompt management or optimization.

Observe → Optimize5/10

Luna-2 proprietary small models for cheap evaluation and an Insights Engine that surfaces patterns, but no prompt optimization and experimentation is manual.

Manual → Autonomous6/10

Galileo Protect auto-enforces guardrails at <200ms and Signals proactively detect failures, but core improvement workflow is human-driven.

Galileo
Scorable AI$2.8M

Evaluation platform with a unique Proxy that intercepts and auto-improves individual LLM responses before delivery, fixing symptoms per-response but not root causes per-system.

Observe → Optimize6/10

30+ Root Evaluators with Evaluator Discovery Agent that generates eval stacks from plain English, plus Proxy that auto-refines responses inline but treats symptoms not root causes.

Manual → Autonomous6/10

Insights engine proactively surfaces failure patterns to Slack and Proxy autonomously refines every response, but no system-level auto-detection or patching.

Scorable AI
Arize AI$131M

Enterprise observability with Alyx AI copilot for failure pattern surfacing and Prompt Learning that generates prompt variants via meta-prompting for human review.

Observe → Optimize6/10

Alyx copilot provides on-demand RCA and Prompt Learning generates prompt variants via meta-prompting, but produces a menu of options without ranking or expected impact. Human picks winner and promotes.

Manual → Autonomous5/10

Online Evals auto-score production traces every 2 minutes, but optimization requires manual dataset prep, 5 example annotations, and triggering each loop. Auto-triggered experiments "Coming soon."

Arize AI
Opik$65M

Open-source platform by Comet ML with 6+ prompt optimization algorithms mostly wrapping Stanford DSPy research (MIPRO, GEPA), own MetaPrompt optimizer is basic.

Observe → Optimize8/10

MIPRO, GEPA, Evolutionary, and Few-Shot Bayesian algorithms adapted from open-source DSPy research with Tool/MCP optimization, but no root cause analysis or learning loop.

Manual → Autonomous6/10

Online evaluation rules auto-score production and alerts fire on thresholds, but all optimization runs are manually triggered and "closing the loop" is future roadmap.

Opik
SentrialYC W26

Agent monitoring that auto-detects 7 issue types, runs root cause analysis, and generates code fixes through an AI chat that knows your codebase so you review the diff and merge.

Observe → Optimize7/10

Auto-detection of 7 issue types with automated RCA, code context linking, and AI chat that generates diffs and creates PRs, but no validation against test data or scientific comparison.

Manual → Autonomous6/10

Sessions are analyzed in real-time with auto-flagging and categorization, but detection is less autonomous than Raindrop (no classifier system) and remediation requires human click and PR review.

Sentrial
Mutagent

Local development, agent factory in the cloud. Connects to your AI systems, finds what is broken, diagnoses why, and delivers validated fixes, all through your existing coding agent. First improvement in under 30 minutes.

Observe → Optimize9/10

Closed-loop optimization: discovers failures from traces, diagnoses root causes, mutates prompts and code, and validates every fix against holdout data before shipping. Every other tool stops at showing you the problem.

Manual → Autonomous9/10

Closed-loop from trace ingestion to merged PR. Works through your existing coding agent (Claude Code, Cursor). Compounds over time. Optimization that takes hours in week one takes minutes by week four.

Mutagent
ObserveLogs and traces. Shows what happened, no quality judgment. DiagnoseExplains WHY it failed. Root cause analysis, failure patterns. OptimizeGenerates, tests, and applies fixes automatically. Closes the loop.

Specialised coding harness for AI engineering

Mutagent runs the development lifecycle automatically. It is the infrastructure that sits on top of all six stages so one standard covers an agent from first draft to production.

Diagnose root-cause before optimisation

Opik, Arize and DSPy run blind search. Mutagent does root cause analysis first, then scopes each change to a diagnosed origin in the harness: prompt, tool, code, or architecture.

Build evaluation system and good test coverage

Competitors bring you an eval framework and assume you have the criteria; Mutagent derives criteria and datasets from your own traces, then proves every change on held-out splits.

Develop and test on local, run at scale in the cloud

Developer experience: Mutagent runs locally in a specialised coding harness, then scales the same system to the cloud, auto-configured through an agent-first CLI.

Benchmark FinanceQA: Mutagent +11.6%, Opik HRPO 0%, GEPA 0% · LegalBench: Mutagent +4.96%
Traction & Validation

Live product in 8 weeks. 100% pain validation. 3 design partners committed.

100% AI-generated codebase, fully tested and functional. First two product features launched. 21 companies in pipeline for second feature. First design partner signed.

Setup

February

  • Product conceptualization
  • Architecture & system design
  • Agentic coding & agentic org setup
  • 20 structured discovery interviews
Build & Validate

March

  • Build & launch first feature for prompt optimization
  • Basic product for setup and prompt optimization
  • 6 SDK integrations, 4 obs connectors
  • Evaluate second feature for AI agents with first design partner
Now

April

  • Prompt Optimization Feature is live
  • 3 design partners committed, 12 in active conversation
  • 27 companies in pipeline for agent-loop optimization (alpha June)

Active

3 active design partners
KalasarKalasar hellotheohellotheo
GetCleraGetClera

Pipeline

27 total in pipeline · 12 highlighted
LangdockLangdock
HeytentHeytent
AArtificial CFO
LunaLift AILunaLift AI LioLio Compound LawCompound Law
ParloaParloa
FINNFINN
ZenMLZenML
KertosKertos
CodycoCodyco
OpenClawOpenClaw
Business Model

Pay per insight. Scale with your agents.

Every analysis is one insight. As users interact through the agent, they continuously consume tokens, spending credits with most actions.

1 Analysis of Execution = 1 Insight

Setup

Insights through development of eval criteria and datasets

Optimize

Insights for benchmarking, RCA & validation

Watch

Insights for every analyzed trace

Free

$0/mo

1,000 insights/mo · Hard cap

Unlimited setups & optimizations

Full API access

Community support

Scale

$199–$13,999/mo

Free plus:

2,000–2M insights/mo (tiered)

Continuous monitoring

Advanced analytics

Email support

Enterprise

Custom

Scale plus:

SLA + dedicated support

On-premise deployment option

Custom integrations

ZERO LLM COST

>90% gross margin through zero internal LLM cost

Customers bring their own model API keys. All optimization agents run on their infrastructure. We carry zero inference cost and keep pure software margins.

EXPANSION

Usage grows with the customer and their agents

Teams add agents over time. More agents in production means more continuous monitoring, more insights, higher tiers. Revenue expands without additional acquisition cost.

CUSTOMER ROI

Customers net 7× their subscription

A 2-person AI team running 3 production agents generates ~30k insights/mo = $749 on the Scale tier. Those engineers were spending 3–4 days/month each on manual trace analysis (~$5,000/mo at $150K loaded cost per engineer). 7× return, before quality and cost-per-token gains.

Go-to-Market

82% of teams have no eval tooling. We solve the adoption barrier itself.

One PLG motion. Four concurrent layers.

ACQUISITION

Free tier + developer channels

  • Permanent free tier (1k insights/mo, full API)
  • Developer communities: Discord, HN, Reddit
  • Obs integrations (Langfuse, Arize, Datadog) at high intent
ACTIVATION

30-minute first improvement

  • npm install via coding agent
  • First validated fix in <30 min
  • Optimization report = artifact developer shows team
EXPANSION

Usage-triggered sales

  • Free-tier cap → in-product upsell
  • High-usage signals → sales reach-out
  • Net retention compounds with agent count
ENTERPRISE

Enterprise follows engineers

  • Multiple teams already running → buyer enters
  • Design-partner case studies as proof
  • Optimization history = structural switching cost
Ideal Customer Profile

Startups & scaleups

Production LLM features. 5–50 employees, seed to Series B. Spending 3–4 dev-days/agent/month on manual optimization today.

AI agencies

Building AI automations for clients. 5–100 employees. Repeatable optimization compounds across every project.

Autonomous AI reliability engineering. The dark magic AI engineers wish they had at 2am.

The Team

The team that lived the problem. Now building the solution.

Deep expertise in AI agents, product-led growth, and AI-native.
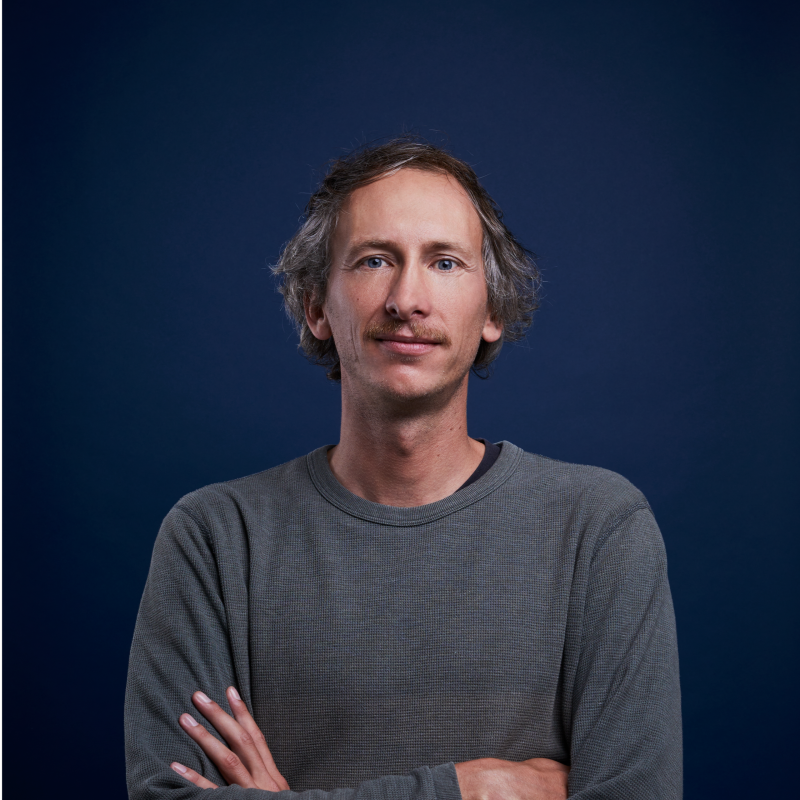
Dr.-Ing. Benedikt Sanftl

Dr.-Ing. Benedikt Sanftl

CEO

Vision, strategy, business development, fundraising.

PhD + 6 patents + 15 IEEE pubs. Staff TPM at Cruise: $250M R&D budget, 40-person team. CPO at Beam AI.

Burak Ozafsar

Burak Ozafsar

CTO

Software architecture, product development, AI research.

Chief Software Architect at Beam AI: built the agent framework and evaluation methodology from scratch. His autonomous coding system generated Mutagent’s MVP in 4 weeks.

What we shipped together

2.5 years

building AI agents at scale

30+

enterprise customers served

98%

agent accuracy in production

10K+

production agent executions monthly

Vision

We start with optimization. We're building the AI Agent Engineer.

Every optimization generates knowledge: failure patterns, successful architectures, validated mutations. We call this Agent DNA. The longer Mutagent runs, the more it knows about how to build, test, and improve agents, until it can scope them from scratch.

Setup Optimize Watch Full AI Engineer

Setup

Map your agent system, discover every tool, prompt, and routing path. Understand the baseline before changing anything.

Optimize

We are here

Auto-research that diagnoses failures, mutates agents, and validates against real data. Ships improvements that you approve.

Watch

Continuous monitoring on auto-pilot. Detect regressions before users do. Every cycle feeds knowledge back into the next.

Full AI Engineer

The autonomous partner for the entire agent lifecycle: from building new agents to optimizing, maintaining, and evolving them in production.

The Ask

Three milestones over 18 months, a clean path to scale.

Revenue-gated hiring, ~425 paying customers, $2.3M ARR.

Month 6

PMF Signal

€16K MRR

~60 paying customers · avg ~€270/mo

  • Design partner cohort validated; first paying customers on the platform
  • Agent-loop optimization launched
  • Repeatable onboarding that delivers first value in <30 minutes
Month 12

Repeatable Growth

€60K MRR

~€724K ARR · ~160 paying customers

  • "Watch" continuous optimization launched
  • Measurable PLG funnel: landing → install → first improvement → paid conversion
  • Self-serve upgrade path proven
Month 18

Scale & Series A

€190K MRR

~€2.3M ARR · ~425 paying customers

  • Team scaled from 3 founders to ~12, every hire revenue-gated
  • Proven unit economics; expansion revenue compounding through self-serve
  • Raise Series A at this milestone

Let's talk about how Mutagent is building the autonomous AI Engineer.

Talk to Founders bene@mutagent.io